Improving Syllogistic Reasoning in LLMs: Activation Steering & Logic Solvers
Content
Improving syllogistic reasoning in LLM logic inference
Large Language Models (LLMs) possess vast world knowledge, but this often harms their ability to perform strict logical deductions. A prime example is syllogistic reasoning, where LLMs struggle with the content effect: rejecting logically valid conclusions simply because they contradict learned real-world facts.
In this post, I explore two methods to fix this: Activation Steering and Neuro-symbolic logic solvers. This writeup is based on a group project I did with two friends of mine for a course on natural language processing. Unfortunately, deadlines did not line up and we finished our project after the official SemEval 2026 competition deadline for task 11, meaning we were unable to submit our project officially. This blogpost is a condensed writeup of what we did, posted with permission by my co-authors. Some snippets are direct quotes from our final report.
In syllogistic reasoning, a conclusion is drawn from at least one premise. Since the premises do not have to align with facts in the real world, conclusions might contradict world knowledge an LLM has.
The above example is logically valid, but not consistent with world knowledge. Thus, LLMs tend to flag the conclusion as false. This phenomena is known as content effect and the most severe problem our SemEval task aimed to solve.1 Faulty reasoning in LLMs is a substantial obstacle for deployments requiring dependable reasoning, for example formal verification, decision support and automated deduction.
We decided early on to focus our attention on compact open-weight LLMs. While large SOTA models feature higher baseline performance in formal logic, compact models are essential for edge deployment, resource-constrained environments, and low-latency inference. We used Llama-3.2-1B-Instruct and Llama-3.1-8B-Instruct (8 bit) in our project.
Existing literature on LLM content effect
Benchmarking formal logic deduction and logical consistency in LLMs has become an active area of NLP research. Prior literature consistently highlights susceptibility to belief bias (e.g. content effects), where models prioritize semantic plausibility over deductive validity. Furthermore, LLMs have been shown to produce human-like reasoning errors, for example falling prey to figural effects like sensitivity to the order of arguments and syntactic arrangements of variables. 2
Effort has also gone into different mitigation strategies: activation steering, a lightweight intervention that biases reasoning by manipulating internal activations 3 can reduce reliance on world knowledge which reduces content effect. Another line of research explores neuro-symbolic AI, pairing an LLM as a semantic parser with a downstream formal reasoning engine. The LLM reads the plaintext arguments and synthesizes them into the input a logical solver expects. The solver then reliably computes the logical correctness 4. Finally, an effort has been made to improve syllogistic reasoning using prompt engineering only 5.
The SemEval 2026 task 11 dataset
The SemEval-2026 Task 11 benchmark consists of categorical syllogisms structured as two premises and a target conclusion, designed to test first-order logical entailment. The data is available in English only. The final system should determine if the conclusion is logically valid given both premises. Additionally, every item had a plausibility label, indicating whether the correct conclusion lines up with world knowledge. This label was used to inform activation steering during training and to calculate evaluation scores.
Task 11 consisted of multiple subtasks, and the lecturer made us choose two. We decided for subtasks 1 and 3: Syllogistic reasoning in English and multilingual syllogistic reasoning. Subtasks 2 and 4 added the inclusion of irrelevant premises to the english-only and multilingual subtasks. The multilingual subtask included languages with a large available corpus like German and Italian, but also languages with less representation in common corpora like Swahili or Bengali. In total, the systems were evaluated on 12 different languages. To evaluate cross-lingual transfer in logical reasoning, we built a translation pipeline using Meta’s facebook/nllb-200-3.3B model to translate the logical deductions into the other typologically diverse languages. We ensured accurate translation by sampling a small subset for each language and checking them by hand.
Evaluating improvements in accuracy and reduction LLM content effects
An evaluation script was provided by the task organizers. It combines a standard correctness metric with additional measures intended to quantify content bias.
Accuracy: Accuracy is the percentage of instances for which the system predicts the correct validity label (valid vs. invalid). This measures overall correctness on the task. The better a model predicts the validity tag, the higher is its accuracy.
Content Effect metrics: Beyond accuracy, the script reports content effect metrics by comparing performance across four subsets:
- plausible-valid: Syllogisms which are both plausible and correct
- implausible-valid: Syllogisms which are implausible but correct
- plausible-invalid: Syllogisms which are plausible but incorrect
- implausible-invalid: Syllogisms which are both implausible and incorrect
A lower content effect is preferable.
The Intra-plausibility content effect measures bias towards a specific label within a plausibility condition:
$$ \begin{equation} \text{Bias}_{\text{intra}} = \frac{1}{2} \left( \left| \text{ACC}_{\text{plausible,valid}} - \text{ACC}_{\text{plausible,invalid}} \right| + \left| \text{ACC}_{\text{implausible,valid}} - \text{ACC}_{\text{implausible,invalid}} \right| \right) \end{equation} $$The Cross-plausibility content effect measures reliance on plausibility within a formal validity condition:
$$ \begin{equation} \text{Bias}_{\text{cross}} = \frac{1}{2} \left( \left| \text{ACC}_{\text{plausible,valid}} - \text{ACC}_{\text{implausible,valid}} \right| + \left| \text{ACC}_{\text{plausible,invalid}} - \text{ACC}_{\text{implausible,invalid}} \right| \right) \end{equation} $$Finally, the Total content effect is calculated as the average of both plausibilities:
$$ \begin{equation} \text{TCE} = \frac{1}{2} \left( \text{Bias}_{\text{cross}} + \text{Bias}_{\text{cross}} \right) \end{equation} $$From there, the final score is computed as:
$$ Score = \frac{\text{accuracy}}{1 + \log(1 + \text{TCE})} $$Methods to improve syllogistic reasoning of Llama 3
We tried two approaches to solve the task, whose results will be compared later. The first is activation steering, and the second is deploying a logic solver in conjunction with an LLM.
Activation Steering
The core idea of activation steering is to modify an LLM’s internal computation by linearly shifting hidden activations in a desired direction. Finding that direction requires a set of labeled training data $D = \{(x_i, y_i)\}_{i=1}^{N}$ where where positive labels reflect logically sound deductions and negative labels represent belief-biased reasoning errors. In our case, we define intended behavior as samples the model classifies correct and wrong predictions as unintended behavior.
I have found the following simplification to be much easier to understand for most people:
Imagine a brain. That brain is put on some medicine, which boosts or reduces the activity in a certain region. For example, medicine against narcolepsy, which boosts certain pathways in the human brain to increase wakefulness. This is roughly what activation steering is doing to the hidden layers of an LLM, but admittedly with less precision. It can still be used to manipulate the LLM’s behaviour. This activation-steering technique is related to what Anthropic did in their research which resulted in Golden Gate Claude.
The major advantage of activation steering is how lightweight it is. It requires much less resources during training than traditional finetuning. Furthermore, it does not significantly increase inference cost and can be conditionally applied on a per-query basis.
Contrastive Activation Addition (CAA)
Contrastive Activation Addition (CAA) is a relatively simple form of activation steering. All activations for both desired and undesired outputs are collected separately. If $\mu^+$ is the average of desired (positive) activations and $\mu^-$ the average of undesired (negative) activations, there difference can be calculated as $\Delta \phi = \mu^{+} - \mu^{-}$. During inference, the model’s activations are modified by adding a scaled version of the contrastive vector: $\tilde{\phi}(x) = \phi(x) + \alpha \cdot \Delta \phi$. $\phi$ is the unmanipulated activation and $\tilde{\phi}$ the final activation with steering applied. $\alpha$ is a scaling factor. This intervention shifts the transformer’s hidden state representations toward activation subspaces associated with unbiased logical deductions.6
Conditional Activation Steering (CAST)
An improvement upon CAA is known as Conditional Activation Steering (CAST). Contrary to CAA, CAST can reverse the direction of the steering vector depending on the input 3. We used condition vectors to determine if $\alpha$ should be positive or negative, the later reversing the steering direction in comparison to CAA.
We worked with two condition vectors $\psi_{c}^{+}$ and $\psi_{c}^{-}$ that are average aggregation of valid and invalid activations. The sign of $\alpha$ is determined by whether the activation is more similar to a valid or an invalid sample.
$$ f \left(\alpha, \phi(x), \psi_c^{+}, \psi_c^{-}\right) = \begin{cases} - \alpha, & \text{ if } \operatorname{sim}(\phi(x), \operatorname{proj}_{\psi_c^{+}} \phi(x)) > \operatorname{sim} (\phi(x), \operatorname{proj}_{\psi_c^{-}} \phi(x)) \\ \alpha, & \text{otherwise.} \end{cases} $$k-CAST: One problem the standard CAST method possesses is that there is some information loss when aggregating all valid and invalid activations vectors during train time. To overcome that, k-CAST utilizes k-nearest-neighbor clustering. Before testing a new sample, all activations from all samples in the training set need to be stored. Then, k-CAST finds the $k = 5$ nearest neighbors within the latent activation space and selects the sign of $\alpha$ based on a majority decision.
Neuro-symbolic logic solver
The second main approach was pairing an LLM with a neuro-symbolic logic solver. The solver performs the actual checking of the logic, guaranteeing correct results given correct inputs. The LLM only needs to translate the syllogism into syntactically valid and semantically correct input, which is something they are quite good at.
We mapped each sentence to exactly one of the qualifiers {all, none, some, some_not} and two unary predicates (a,b) resulting in a compact symbolic representation that is independent of the underlying language. Note that such a compact representation is only possible because the inputs follow the same exact, narrow formal structure shown in the example above. It is not a general-purpose translation of arbitrary natural language into first-order logic.
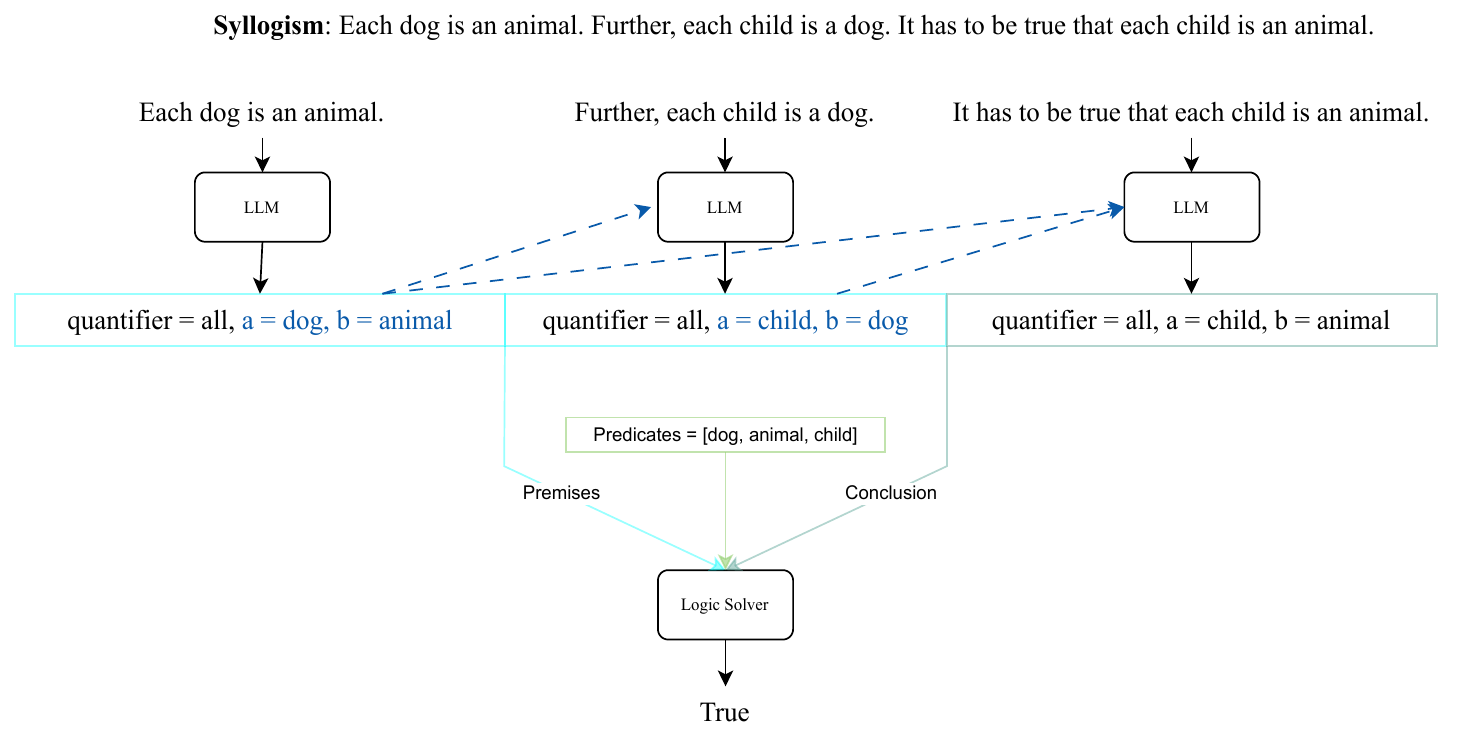
Three-staged data extraction pipeline
For each syllogism, we prompted the LLM to extract a quantifier and two terms from each of the three sentences. Extracting all three sentences jointly increased formatting errors and occasionally mixed information across sentences, so we performed extraction sentence-by-sentence. To promote consistent terminology, we tracked a short used_predicates list and include it in the prompt, encouraging reuse of earlier predicate names.
Because the logic solver treats distinct strings as distinct predicates, we normalized extracted terms (lowercasing, replacing spaces with underscores, removing determiners conservatively, and singularizing English nouns). We also included the full syllogism in each prompt to further stabilize naming across sentences.
Finally, we validated outputs and passed them to the solver only if they match the required 3-tuple format (quantifier=..., a=..., b=...). Malformed extractions are rare; when they occurred, we fell back to random guessing. This fallback can introduce avoidable errors and increases variance. Here, we should have implemented more sophisticated fallbacks, for example retries, possibly including previous failed attempts to inform the model, or allow the LLM to judge on its own.
Verifying Deductions with the Z3 Logic Solver
We used Microsoft Research’s Z3 highly efficient SMT (Satisfiability Modulo Theories)-solver, to verify whether premises logically entail the extracted conclusion. Given the parsed terms of a syllogism, Z3 returned a binary verdict (valid or invalid), which served as the final output of our pipeline.
Handling of multi-lingual syllogistic data
To support the different languages required by our task, we separated language-specific preprocessing from the language-agnostic symbolic representation and extraction. We automatically detected the language and separated the input into 3 sentences using ICU sentence boundary detection before passing the input into the three-staged extraction pipeline. An English extraction prompt performed best across languages, so we used a single, language-independent prompt.
After extraction, we normalize predicate strings using lightweight, language-specific filtering (e.g., removing articles) to reduce superficial variation, without translation or external linguistic resources. These steps consistently yielded suitable input for the solver.
Every manipulation of the natural language input increases the risk of accidentally changing its meaning, and therefore providing wrong input to the solver. As our results show, this problem did not majorly affect us.
LLM choice
We use models from the Llama family. In our experiments, Llama-3.2-1B-Instruct proved unreliable for structured extraction (e.g., it often outputs some instead of some_not), so we additionally evaluated Llama-3.1-8B-Instruct in 8-bit quantized form. Both models are fast and require few resources, enabling low-latency or low-resource deployment.
Results: Activation Steering vs. Logic Solvers
Experiments were conducted using five different seeds (10, 20, 30, 40, 42). The dataset was split 90/10 between training and evaluation (for activation steering). Since training only requires calculating steering vectors it can be performed quite quickly. On a single A100, training and evaluation across all languages and English-only finished within a few minutes, including evaluation for the Neuro-symbolic logic solver. No training was required for the later.
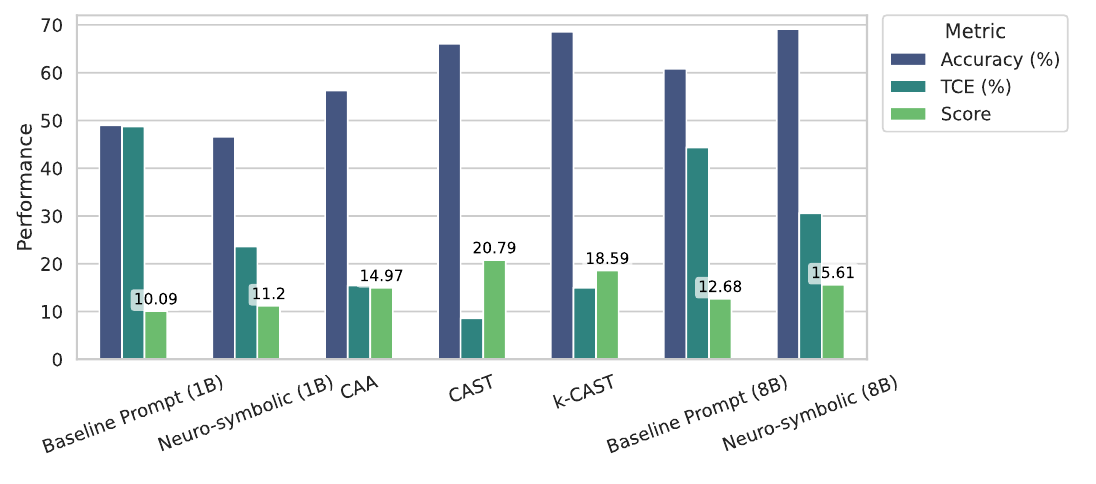
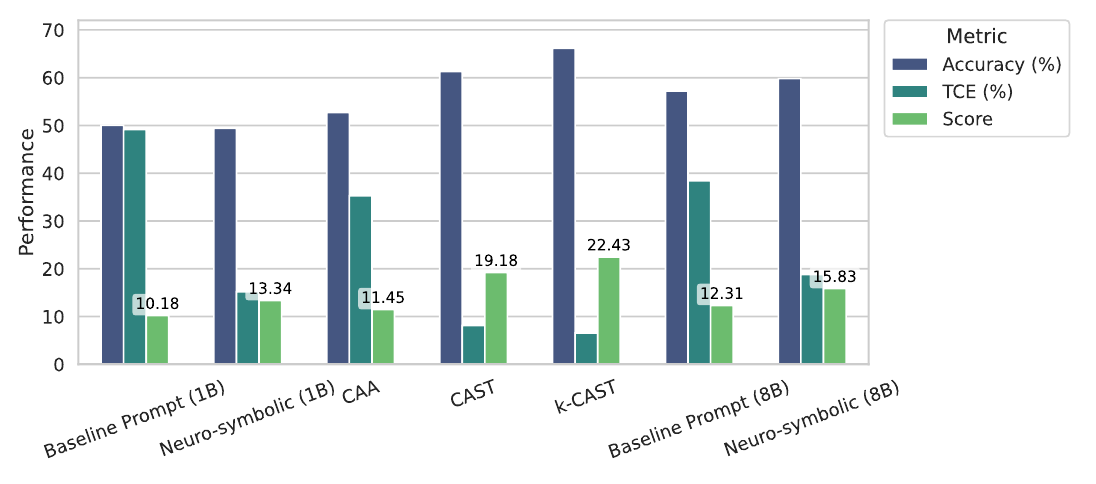
For reference, evaluation includes a baseline which just prompted the LLM.
Activation Steering
The activation steering approach consistently outperformed both the baseline and neurosymbolic approaches. In the English-only setting, the highest score was achieved by CAST, even though k-CAST attained higher overall accuracy. We attributed this discrepancy to limited training data: k-CAST may not have sufficient examples to reliably inform its condition detection, leading to less robust decisions under the primary evaluation metric.
In the multilingual setting, k-CAST surpassed CAST, plausibly because mean-vector-based condition detection becomes substantially noisier when aggregating activations across languages. This improvement comes at a computational cost: k-CAST requires loading activations for all training samples to perform condition detection and computing k-nearest neighbors for each query activation. These requirements can be expensive, particularly when scaling to larger datasets.
Neuro-symbolic logic pipeline
For the neuro-symbolic pipeline, we observed only little improvement over the baseline when using Llama 1B. We attributed this mainly to errors in the logical-form translation stage and to the limited capacity of the 1B model, which appears unable to perform this mapping reliably. Replacing Llama 1B with a larger variant (8b quantized) substantially improved performance, indicating that model capacity is a key factor for this approach.
- Llama 1B (Underperformed): Showed little improvement over the baseline. We attribute this to errors during extraction and generating of Z3 solver input, as the 1B parameter model struggled to map premises reliably.
- Llama 8B (Improved Accuracy): Substantially improved accuracy in both data settings, with a pronounced increase on English data.
- Total Content Effect (TCE): Interestingly, while Llama 1B had a worse baseline TCE, it achieved better TCE under the neuro-symbolic constraints than the 8B model. This indicates the smaller model’s logical decisions are less influenced by semantic plausibility.
Conclusion
In our project, we demonstrated that substantial improvements in LLM logic inference are possible using multiple techniques. For me personally, Activation Steering stood out as very versatile and low-overhead tool to manipulate a model. Unlike prior representation engineering experiments (such as Anthropic’s Golden Gate Claude) that manipulate conversational personas or topical features, our work demonstrates how activation steering can directly steer cognitive reasoning capabilities. This is an important demonstration towards improving specialization of models on-demand. In the future, I would love to further explore AI explainability and how an improved understanding could be use to make models safer and better.
See e.g. Dasgupta et al., Language models, like humans, show content effects on reasoning tasks ↩︎
See e.g. Bertolazzi et al., A Systematic Analysis of Large Language Models as Soft Reasoners: The Case of Syllogistic Inferences ↩︎
See e.g. Valentino et al., Mitigating Content Effects on Reasoning in Language Models through Fine-Grained Activation Steering ↩︎ ↩︎
See e.g. Pan et al., Logic-Lm: Empowering Large Language Models with Symbolic Solvers for Faithful Logical Reasoning ↩︎
See e.g. Ranaldi et al., Improving Chain-of-Thought Reasoning via Quasi-Symbolic Abstractions ↩︎
See e.g. Rimsky et al., Steering llama 2 via contrastive activation addition ↩︎
#llms #machine learning #activation steering #neuro-symbolic ai #nlp #local llms